Category: AI Providers

Honest reviews of the AI models and providers that power website chatbots — Gemini, OpenCode Go, and Gemma free tiers compared on pricing, limits, and quality.

  • Command Code Pricing Review: Plans, Limits, Credit Value (2026)
    ▶ Listen to this article

    Command Code is the agentic coding platform from commandcode.ai — a CLI and Studio toolset that wraps Anthropic, OpenAI, Google, MiniMax, DeepSeek and dozens of open-weight models behind one interface. Its pricing model is the most interesting part of the product: flat monthly subscription with a MASSIVE credit multiplier, rolling usage windows, and credits that never expire. This is my honest command code pricing review after reading the full pricing and limits documentation cover to cover.
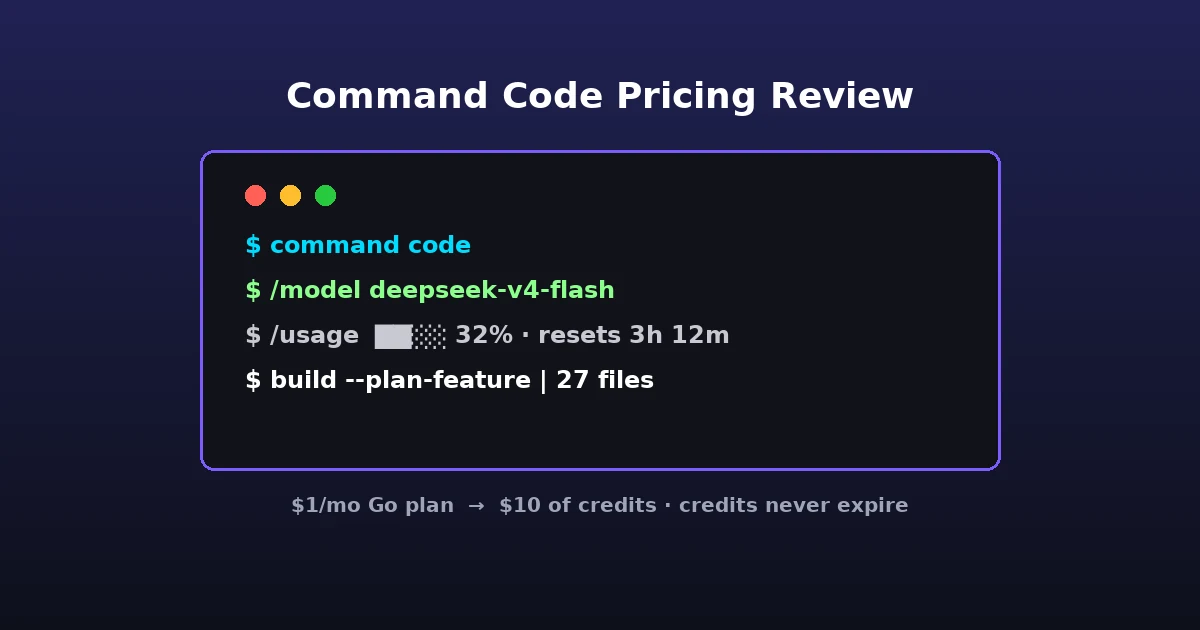
    command code pricing review hero

    What Is Command Code?

    Command Code is an AI coding agent that runs in your terminal (CLI) and in a desktop Studio plus IDE integrations. You bring your own project, Command Code reads your codebase, and lets you plan, write, review and fix code using the model you pick. It is not a chatbot website widget — it is a developer tool aiming to replace the paid tiers of Anthropic and OpenAI coding planes with a subscription that bundles access to many models at once.

    The key architectural choice: instead of a fixed monthly model fee, Command Code sells you a credit pool at a steep multiplier. You then spend those credits per token, per model, at the model’s own API rate. This is the same “buy a pool, spend by model” structure as OpenRouter, but wrapped in a flat monthly plan where the credits are heavily subsidized.

    Command Code Pricing: The Plans at a Glance

    The documentation on the Command Code pricing and limits page lists six individual plans and two team plans. Here is the real table from the doc:

    PlanPrice/moCredits/moApprox requests5-hour limitWeekly limit
    Go$1$10~9K$2$5
    GOAT$10$70~75K$14$35
    Pro$20$80~100K$16$40
    Provider$15Pay-as-you-go———
    Max 10×$100$150~230K$45$90
    Max 20×$200$300~370K$90$180
    Team Pro$40~35K requests—$12$24
    Enterprise$5,000+CustomCustom——
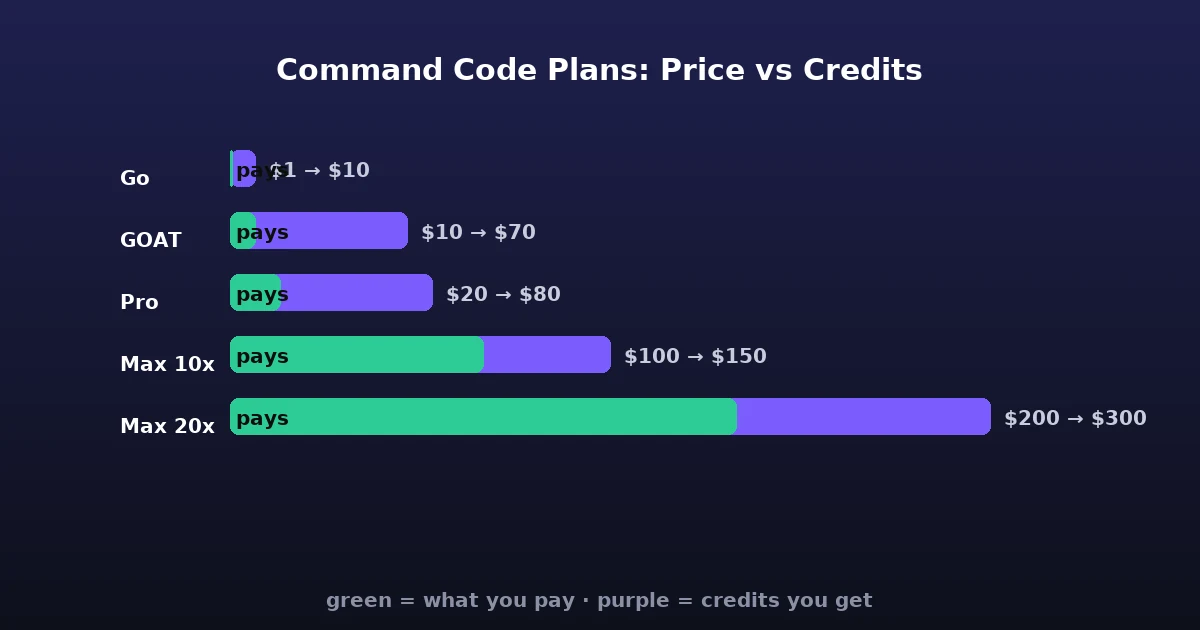
    command code pricing plans price vs credits

    How the Credit Multiplier Actually Works

    This is the single most surprising thing about command code pricing. On the Go plan you pay $1 and get $10 of credits. On GOAT you pay $10 and get $70. On Pro $20 for $80. Max 10× is $100 for $150, Max 20× $200 for $300. That is a 10× to 1.5× credit bonus depending on tier.

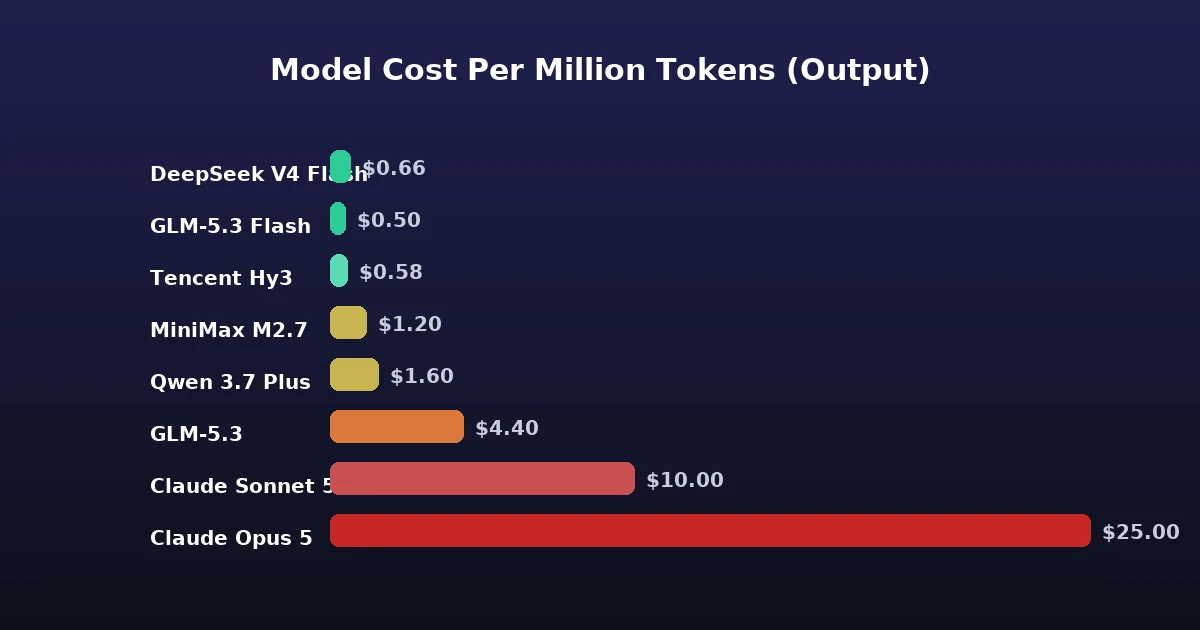
    The credits are then spent at the model’s own per-token API rate. A cheap model like DeepSeek V4 Flash at $0.15 input / $0.60 output per million tokens (off-peak) stretches much further than Claude Opus 5 at $5.00 / $25.00. Command Code’s own estimate: on Go, DeepSeek V4 Flash runs about 25,000 requests with no cache, or ~15,000 once the typical 50K of cache reads are counted.

    Rolling Usage Windows: The Hidden Constraint

    Every subscription plan has two rolling limits on top of the monthly credit pool: a 5-hour window and a weekly window. They are designed to stop a single burst from draining a whole month in one afternoon.

    Here is the tradeoff you need to understand before buying: your monthly credits are not immediately spendable all at once. On Go, the 5-hour window caps you at $2 of usage and the weekly window at $5 of your $10 pool. On Max 10× you can spend $45 in 5 hours and $90 a week out of $150. Windows roll from first use, not on a fixed clock, and reset each window-length.

    The good news: on-demand top-up credits are exempt from the rolling windows. If you hit a window mid-session you can buy extra credits and keep working immediately, with the window check skipped entirely.

    Do Credits Really Never Expire?

    Yes — that is stated plainly. Monthly subscription credits reset at the start of each billing cycle, but top-up and on-demand credits roll over forever. They are not throttled, not capped, and you can buy them at model cost. This is genuinely consumer-friendly for a pay-per-usage product and a real differentiator versus many competing plans that expire credits monthly.

    Model Pricing: The Depth of the Catalog

    Command Code’s catalog is deep. Across all plans the docs list 89 models at the time of writing, with 7 deals and 5 free models. The newest head is Claude Opus 5.5 at $4.00/$20.00 per million tokens — cheaper than Claude Opus 5 — alongside GPT-6 Sol and the budget GPT-6 Luna, and MiMo V2.6 Pro and Flash. Here is what matters for real coding work:

    Premium frontier models

    ModelInput/MOutput/MCache read/MCache write/M
    Claude Opus 5$5.00$25.00$0.50$6.25
    Claude Sonnet 5$2.00$10.00$0.20$2.50
    Claude Haiku 4.5$1.00$5.00$0.10$1.25
    GPT-5.6 Sol$5.00$30.00$0.50$6.25
    Claude Opus 5.5 (1M ctx)$4.00$20.00$0.20$5.00
    GPT-6 Sol (1.1M ctx)$2.00$10.00$0.20$2.50

    Cost-efficient workhorses

    ModelInput/MOutput/MCache read/M
    DeepSeek V4 Flash (off-peak)$0.15$0.60$0.003
    DeepSeek V4.1 Flash$0.15$0.60$0.003
    DeepSeek V4 Pro (off-peak)$0.66$1.98$0.022
    GLM-5.3 Flash$0.15$0.50$0.03
    MiniMax M2.7$0.30$1.20$0.06
    Qwen 3.7 Plus$0.40$1.60$0.08
    Tencent Hy3$0.14$0.58$0.035
    MiMo V2.6 Flash$0.14$0.28$0.0028
    MiMo V2.6 Pro$0.435$0.87$0.0036
    GPT-6 Luna (1.1M ctx)$0.10$0.50$0.01
    command code pricing model costs per million tokens

    Free Models in 2026: Real Zero-Cost Coding

    At the time of writing, Command Code had five free models — some permanently, some time-bound. (LongCat 2.0, free when this review was first written, has since moved to a standard per-token rate, which is a good reminder that this roster rotates.)

    • Space Bunny Alpha — free while the stealth preview lasts (1M context, input/output/cache all $0.00). It is a stealth model: an anonymous third-party provider runs it, may retain prompts and completions, and offers no zero-data-retention guarantee — so it is deliberately excluded when you run with CMD_ZDR=1.
    • Ling 3.1 Flash — free while it lasts, with no daily request limit (262K context, input/output/cache all $0.00). It is inclusionAI’s hybrid reasoning model, aimed at coding and multi-step work.
    • Laguna S 2.1 — free while capacity lasts, available on all plans (input, output and cache reads all $0.00).
    • Ling 3.0 Flash — free while capacity lasts (256K context).
    • Ling 3.0 Flash Sante — free while it lasts, up to 100 requests a day (262K context, health-and-medicine tuned).

    One caveat worth knowing before you rely on the free lanes: the free variants are served by third-party hosts (e.g. Novita for Ling 3.0 Flash Sante, which carries a 100-requests-per-day cap) that offer neither zero-data-retention nor a no-training guarantee, and Space Bunny Alpha is served by an anonymous stealth provider that may keep prompts. If you run with CMD_ZDR=1 to force zero retention, you cannot use those free lanes at all. The free models are limited-capacity offers, so treat them as a nice bonus, not a dependable base.

    Active Deals That Change the Math

    The docs flag seven deals live at the time of writing that can stretch your credits dramatically:

    • kimi-k3 boosted credits — $60 of usage on GOAT (up from $20) and $70 on Pro (up from $30), through October 7, 2026.
    • glm-5.3-flash boosted credits — $10 on Go, $60 on GOAT and $70 on Pro, while capacity lasts.
    • minimax-m3 at 2× usage — every credit goes twice as far.
    • mimo-v2.5 and mimo-v2.5-pro up to 99% off.
    • stealth/space-bunny-alpha, laguna-s-2.1-free, ling-3.0-flash-sante:free and ling-3.1-flash-free are free — requests on those four lanes cost no credits at all and do not draw down your usage windows (see the free-model caveats above).
    • deepseek-v4.1-flash boosted credits, now with no end date — $10 of this model on Go, $60 on GOAT and $70 on Pro. The doc has made the boost permanent and it applies automatically.

    Deals stack with your plan’s credit bonus. On GOAT and Pro the deals are baked into per-model allowances automatically, with nothing to enable. On top-up credits the same discount applies when spent on the discounted model. The real-time Usage page shows the discounted per-request price as it happens, and deals auto-expire with no action needed.

    Enterprise and Security

    For organizations, Command Code offers an Enterprise tier from $5,000+/mo with custom model pools, SLAs and dedicated support on your own infrastructure. The documented security posture is strong for a coding agent: Command Code does not train on your code and does not store your code snippets unless you choose to share them. Taste data (your personalization) is stored locally in your project directory. Commercial model traffic is sent to the provider’s API (Anthropic, OpenAI, Google, Azure) and handled per their privacy policy, with EU hosting on demand. There is a Zero Data Retention mode available, subject to the free-lane caveat above.

    How Command Code Compares to Other Providers

    If you already use OpenRouter or Google AI Studio’s free tier, Command Code is a different category. OpenRouter is a pure API gateway: you pay per token with no subscription bonus. Google AI Studio gives you a limited free tier. Command Code bundles a subscription plus access to both open-weight and premium models, with the credit multiplier as the main incentive. The closest analogues are the paid coding plans of Anthropic and OpenAI, but Command Code’s advantage is model choice and the never-expiring top-up credits.

    For a website owner or chatbot operator rather than a developer, Command Code is not the tool for adding a chatbot to WordPress — that is a code-heavy workflow. But if you are building, deploying or maintaining that chatbot’s backend, plugins, or n8n workflows, a cheap Go plan gives you a serious coding agent for a dollar a month.

    Who Should Buy Which Command Code Plan

    • Go ($1/mo, $10 credits) — hobbyists, light script editors, first try. Enough for dozens of small tasks and a real test of the workflow.
    • GOAT ($10/mo, $70 credits) — the best value if your work is mixed open-weight coding. ~75K requests.
    • Pro ($20/mo, $80 credits) — heavy users who want premium models like Sonnet 5 and GPT-5.6 in the mix. ~100K requests.
    • Max 10×/20× ($100/$200) — professional teams hammering code all day; the credit multiplier is weakest here (1.5×) but the pool is biggest and windows are generous.
    • Provider API ($15) — pay-as-you-go raw API access, no subscription, for integration into your own apps.

    Limitations and Honest Caveats

    • Rolling windows are real throttles on included credits. Your 10× credit bonus is not instantly spendable — on Pro you cap at $16 per 5 hours. Plan around bursts.
    • Free models are capacity-limited or time-bound. Laguna S 2.1, Ling 3.0 Flash and Ling 3.0 Flash Sante are all “while they last” or daily/request-capped offers.
    • No zero-retention on the free lanes. The free models are served by third-party hosts with no ZDR/no-training guarantee.
    • A developer tool, not a chatbot provider. If you want to embed a chat widget on your site, this is not that. It is for writing code.
    • Request estimates vary wildly. 9K vs 25K vs 370K depends entirely on model choice and cache usage. The “typical request” includes ~42-56K cache reads that burn credits on every turn.

    A Worked Example: What One Session Costs

    To make the numbers concrete, let me run a realistic session through the pricing. Command Code states a typical request is about 700-1,000 input tokens, 125-200 output tokens, plus roughly 42,000-56,000 cache reads on average. The cache reads are the quiet cost driver: every new turn in a conversation re-reads the full context, so a long-running session is far more expensive than a fresh one.

    Take three models doing the same 50-request feature build:

    ModelInput costOutput costCache cost~50 requests
    DeepSeek V4 Flash$0.15/M$0.60/M$0.003/M~$0.65
    Claude Sonnet 5$2.00/M$10.00/M$0.20/M~$11
    Claude Opus 5$5.00/M$25.00/M$0.50/M~$27

    The gap is enormous: the same build costs roughly 40× more on Opus than on DeepSeek Flash. That is why Command Code’s “how far your credits go” is genuinely model-dependent, and why the docs repeatedly steer you toward cheaper models when you want many requests rather than maximum quality. It also means the monthly-request estimates (9K on Go, 75K on GOAT, 100K on Pro) are useful only if you favor efficient models. Pick ambitious premium models all day and you will burn the pool far faster.

    A practical tip from the docs: start a new session (or use /clear) for unrelated tasks, because every new turn re-reads the full context in cache. Keeping conversations short is the single biggest lever on cost.

    How Command Code Stacks Up Against Other Providers

    Because I review AI providers for yakwp.com, I have tested several of the alternatives Command Code competes with, and the differences matter depending on what you are building.

    Command Code vs OpenRouter

    OpenRouter is a pure API gateway: you bring your own key and pay per token with no monthly subscription, no credit multiplier, and no free-tier coding models of its own. If you want direct API access to many models for your own application — such as the plumbing behind a WordPress chatbot — OpenRouter is the more direct choice. Command Code instead gives you a subsidized flat plan, which wins when you want a lot of coding done for one predictable monthly price. My OpenRouter review covers that tradeoff in depth.

    Command Code vs OpenCode Go

    OpenCode Go is the closest direct competitor: an agentic coding CLI with bundled model access at a low flat price. Both use a subscription-plus-many-models model. Command Code’s pricing documentation is unusually transparent (public per-token rates for all 89 models, real-time usage meters, rolling windows), which is a point in its favor for cost-sensitive developers. See my OpenCode Go review for the alternative.

    Command Code vs Google AI Studio

    Google AI Studio’s free tier is the standing reference point for zero-cost AI: a generous daily free allowance on Gemini models. It is free but limited to Google’s models. Command Code bundles a much wider catalog (Anthropic, OpenAI, DeepSeek, Qwen, MiniMax and more) behind a paid subscription, with only a few free models. If you want Google models for free, Google AI Studio’s free tier is still the unbeatable option; if you want a broad multi-model coding agent, Command Code wins.

    All three reviews live in our AI providers cluster, so you can compare the whole field.

    Who This Is For (and Who It Is Not For)

    Command Code is squarely a developer tool. It makes sense for developers, technical founders, and automation builders who write, review and maintain code every day.

    It is not the tool for adding a chatbot to your website, embedding a support widget, or sending visitors an AI assistant. For those, a WordPress chatbot plugin with its own model integration is the right starting point — and I recommend seeing how to add an AI chatbot to WordPress and our best free chatbot roundup. But if you are building the backend, plugins, or n8n automation behind that chatbot, a $1 Go plan gives you a serious coding agent to do it.

    Command Code Pricing: Final Verdict

    Putting the whole model together, here is how I rate Command Code across the dimensions that matter:

    DimensionRatingNotes
    Value / dollarExcellent$1 → $10 of credits; ~10× multiplier on low tiers
    Price transparencyExcellentAll 89 model rates public; real-time usage meter
    FlexibilityExcellent89 models, BYO providers, switch with /model
    Credit longevityExcellentTop-up credits never expire
    Burst friendlinessFairRolling 5-hour / weekly windows on included credits
    Free tierGood5 free models, but capacity-limited / time-bound
    Audience fitNarrowDevelopers only; not a chatbot-widget provider

    Frequently Asked Questions

    Is Command Code actually free?

    The software has a $1/mo Go plan and several free models. Five models are free at the time of writing — Laguna S 2.1, Ling 3.0 Flash, Ling 3.0 Flash Sante, Space Bunny Alpha and Ling 3.1 Flash — all while capacity or the preview lasts, or under a light daily cap. You need at least $1 of credits to start a session.

    Do Command Code credits expire?

    Monthly subscription credits reset each billing cycle, but top-up and on-demand credits roll over forever and never expire.

    Which Command Code plan is best value?

    GOAT at $10/mo for $70 of credits is the strongest multiplier for mixed open-weight work. Pro is better if you want premium models included.

    What models does Command Code support?

    89 models across Anthropic, OpenAI, Google, xAI, DeepSeek, MiniMax, Qwen, GLM, Kimi and Tencent, plus five free models and seven active deals.

    Is Command Code safe to use with my code?

    Yes. Command Code does not train on your code or store your code snippets unless you choose to share them. Taste data is stored locally. Zero-data-retention mode covers 99% of the catalog; the free lanes and the anonymous Space Bunny Alpha stealth preview fall outside it and are refused when you run with CMD_ZDR=1.

    Conclusion

    Command code pricing is cleverly designed: a flat subscription with a big credit multiplier, model-level per-token spend, and never-expiring top-ups. The value is real on the low tiers — a dollar for $10 of credits is a genuinely good deal for light coding. The rolling windows keep that generosity honest, and the free model selection makes it easy to try with zero risk. The main thing to remember is that this is a coding agent, so it serves yakwp’s audience best as a backend tool for building the automations, plugins and n8n workflows behind a WordPress chatbot, not as the chatbot itself.

    If you need a solid, cheap alternative to expensive Anthropic or OpenAI coding plans — or you want access to dozens of models behind one subscription — Command Code is worth a serious look. Start on the $1 Go plan, test the free Laguna S 2.1 model, and upgrade only when the usage windows start to bite.
  • OpenRouter Review: 466 AI Models, a Real Free Tier, No Subscription

    ▶ Listen to this article

    Server data center hosting AI models
    One gateway in front of hundreds of model providers.

    This is an in-depth OpenRouter review born from real testing: one API key, 466 models, no subscription, and a free tier that actually works.

    I have spent years juggling model APIs. Separate accounts at OpenAI, Anthropic, Google, then a half dozen smaller providers, each with its own dashboard, its own billing, its own rate limit table I was supposed to memorize. Every new model meant another signup. OpenRouter fixes exactly that, and it has a genuinely usable free tier that most people never find.

    This is the review I wish I had before I hit the signup page. Real numbers from the live API, the free models that are actually worth your time, the rate limits that matter, and the honest cases where you should skip it.

    What OpenRouter is

    OpenRouter is a gateway. Not a model company. It sits in front of hundreds of open and proprietary models and serves them all through one OpenAI-compatible endpoint.

    When you call a model, OpenRouter routes to the provider hosting it, and if that provider is down, the request falls over to the next one automatically. You get one key, one invoice, one analytics dashboard. The providers change underneath you. The interface does not.

    The free tier is the real story

    Here is what most review pages get wrong about OpenRouter. The free models are not demos. As of this month the API lists 22 models at $0 — 17 carrying a :free build, plus the free-model router, two Google Lyria audio previews, one stealth model (Space Bunny Alpha), and inclusionAI’s free Ling 3.1 Flash — and the chat models among them are legitimate production models, not crippled trials.

    The free lineup includes Google’s Gemma 4, NVIDIA’s Nemotron 3 and 3.5 series, Thinking Machines’ Inkling, Qwen 3.8 27B, and more. Four of them carry a full million-token context window — Nemotron 3 Ultra 550B, Nemotron 3.5 Lightning, Inkling and Inkling Small. A million tokens, free. One casualty of the last rotation: Z.AI’s GLM-5.2 lost its free build and is now paid only ($0.02 in / $16.00 out per million), so it is off this list. The roster keeps rotating: inclusionAI’s Ling 3.0 Flash also went paid, and its successor Ling 3.1 Flash is the free inclusionAI entry now.

    Model Context Notes
    Google Gemma 4 31B 262K Reliable general purpose
    Google Gemma 4 26B 262K Lighter, faster
    NVIDIA Nemotron 3 Ultra 550B 1M Biggest free option
    NVIDIA Nemotron 3 Super 120B 262K Strong all rounder
    NVIDIA Nemotron 3 Nano 30B 256K Fast, high volume
    Thinking Machines Inkling 1M New, huge context
    NVIDIA Nemotron 3.5 Lightning 1M Newest free head, huge context
    Thinking Machines Inkling Small 1M Lighter sibling of Inkling
    Qwen 3.8 27B 262K Strong open-weight all-rounder
    InclusionAI Ling 3.1 Flash 262K Fast, light coding and chat
    Poolside Laguna XS 2.1 262K Smaller code model
    Dots 3 Note Preview 512K Huge context
    Cohere North Mini Code 256K Code focused
    Poolside Laguna S 2.1 262K Code generation

    Pick the right free model and you can run real workloads on it. For a prototype, a hobby project, or a low-traffic tool, the free tier alone is enough to launch.

    The rate limits you need to know

    Free does not mean unlimited. Without credits, free models run at 20 requests a minute and 50 requests a day. That covers testing and building. It will not run a public chatbot.

    Here is the trick that changes everything. Buy $10 of credits once, and the daily cap on free models jumps to 1,000 and stays there. The $10 is not consumed by the free models. It simply sits on your account for when you call a paid model. One purchase, and the free tier becomes genuinely usable for the week, not just the afternoon.

    How the billing works

    OpenRouter passes through whatever the model provider charges. There is no markup on the tokens. The company makes its money on the credit purchase itself, not on usage.

    The cheap end of the catalog runs at fractions of a cent per thousand tokens:

    Model Input Output
    Mistral Nemo $0.02 $0.03
    Qwen 3.7 Flash $0.03 $0.13
    OpenAI GPT-OSS 120B $0.037 $0.17
    Cohere Command R7B $0.04 $0.15
    Amazon Nova Micro V1 $0.04 $0.14

    A long running prototype can cost less than a coffee. When you only pay pennies for a thousand tokens, you stop thinking about usage and start thinking about what to build.

    Bring your own key

    If you already pay OpenAI, Anthropic, or Google directly, you do not need to buy OpenRouter credits at all. The BYOK program lets you plug your existing keys into OpenRouter and use it purely as a unified interface.

    That setup gives you a million free routing requests a month. Past a million, OpenRouter charges a 5% routing fee on top of what the provider charges. For one interface over every key I own, with fallback and analytics included, I consider that fee a fair deal.

    Privacy is handled, not promised

    By default OpenRouter logs nothing of your prompts or completions. Not even when a request errors. Only billing metadata, timestamps, and token counts are kept. Your text stays yours.

    There is an opt-in setting that trades that logging for a 1% discount on usage costs. It is off by default, and you have to switch it on deliberately. For a company whose whole business is passing data between you and model providers, that default deserves credit.

    Those model suffixes explained

    The model IDs end in a suffix that tells OpenRouter how to route the call. It looks like noise until you know what they mean.

    • :free uses free tier hosting where available.
    • :nitro routes to the fastest provider.
    • :floor routes to the cheapest provider.
    • :thinking enables reasoning mode on models that support it.
    • :extended routes to a provider offering a longer context window.

    So deepseek-r1:free gets you a reasoning model for nothing, and llama-3.3-70b:floor gets you a paid model at its cheapest source. The suffixes stack on top of any model you already know.

    Where it falls short

    I tested the free tier properly, and I want to be honest about the limits.

    Do not run production traffic on free models. No SLA, hosting can drop out, and 20 requests a minute dies the moment a second user opens your app. The free tier is for building and proving an idea, not for scale.

    The free roster also rotates. A model that is free today can lose its free hosting next month. The :free router picks whatever is available, but you lose the choice of a specific model.

    And the credit purchase fee is the catch. If you spend heavily on a single provider, the direct route is sometimes cheaper. OpenRouter wins on convenience and breadth. It does not always win on pure price.

    Who should use it

    Get it if you compare models, if you build something that might switch providers, or if you want to prototype on free models before paying. Get it if you already hold several provider keys and want one dashboard.

    Skip it if you use one model from one provider and nothing else. The credit fee is pure overhead there, and you are better off going direct.

    FAQ

    Do I need a credit card to start?

    No. The 22 free models work the moment you sign up. Credits are only needed to lift the daily cap or call paid models.

    Is it a drop in replacement for OpenAI?

    Mostly. Point your client at the base URL, drop in your OpenRouter key, and the request format matches. Code that targets OpenAI generally works unchanged.

    What does OpenRouter charge?

    A fee on credit purchases, and a 5% routing fee on usage above a million BYOK requests a month. Model pricing passes through with no markup.

    Which free model is best right now?

    Gemma 4 31B or Nemotron 3 Super for general work. Nemotron 3 Ultra 550B or Nemotron 3.5 Lightning if you need the million token context. North Mini Code or Laguna for code.

    Can this replace my provider?

    If you use several, yes, it replaces most of the friction. If you use one, it is overhead. It is a gateway, not a model.

    The bottom line

    The thing I keep coming back to is the friction it removes. No new account at every lab. No memorizing five rate limit tables. No logging into a different billing page to understand a single invoice.

    One key, and behind it, everything. Start on the free tier, put $10 down if the daily cap bites, and decide from there. If it is not for you, testing it costs nothing at all.

    Sign up at openrouter.ai. No credit card needed to start.

  • Google AI Studio Free Tier Review: 14,400 Free AI Requests

    Google’s free tier just changed twice in quick succession, and both changes matter if you run a website chatbot. First, Gemma 4’s free allowance jumped from 1,500 to 14,400 requests a day — a nearly 10x increase. Then Google dropped in a brand-new model, Gemini 3.5 Flash-Lite, at 500 free requests a day. Both live on the Google AI Studio free tier, the free playground Google runs at aistudio.google.com.

    Google AI Studio free tier abstract AI technology concept
    Free AI tiers keep your costs at zero.

    Here’s what actually changed, and whether either update matters for your site.

    The Headline: Gemma 4 Went From 1,500 to 14,400 Free Requests a Day

    This is the bigger of the two changes and the one most people missed. Until recently, Gemma 4 sat at 1,500 free requests a day on the Google AI Studio free tier. That was already the best free deal around — roughly 3x what the Flash-Lite models gave you.

    Now it’s 14,400 requests a day. That’s almost ten times its old allowance, and close to 29 times what the Gemini Flash-Lite models get at 500. Google essentially turned Gemma 4 from “good free option” into “run a real chatbot on this and never think about the limit again.”

    For a self-hosted WordPress chatbot, 14,400 requests a day is more conversation volume than a small or mid-size site will ever touch. You’d have to average a new message every six seconds, around the clock, to exhaust it. Let that sink in: an allowance you could never realistically hit, at a price of exactly zero.

    The Second Change: Gemini 3.5 Flash-Lite Is Now Free

    Alongside the Gemma bump, Google added Gemini 3.5 Flash-Lite to the free tier at 500 requests a day — the same allowance the older 3.1 Flash-Lite gets. The model launched with 3.6 Flash and is positioned as a low-latency, cost-efficient workhorse for high-volume tasks.

    The “Lite” name means it trades a bit of reasoning depth for speed. For a chatbot, that’s the right trade: a snappy answer usually beats a slightly more considered one. DeepMind calls 3.5 a “huge jump” over 3.1, which is what most free-tier chatbots were running on.

    So the Flash-Lite story is simple: same free price as before, noticeably better output. If you were on 3.1 Flash-Lite, switching to 3.5 is a free upgrade. And because both are one dropdown away in your chatbot settings, there’s no reason not to make the switch today.

    Google AI Studio Free Tier Lineup Right Now

    Here is the full picture from a live aistudio rate-limit panel in August 2026. Per-model limits rotate as Google ships models, so treat this as a snapshot and trust your own panel if it differs.

    Model Free requests / day Role Change
    Gemma 4 31B 14,400 Open-weight workhorse ⬆️ up from 1,500
    Gemma 4 26B 14,400 Smaller Gemma variant ⬆️ up from 1,500
    Gemini 3.5 Flash Lite 500 Fastest polished replies 🆕 new model
    Gemini 3.1 Flash Lite 500 Previous Lite default unchanged
    Gemini 3.7 Flash 20 Frontier test-only unchanged
    Gemini 2.5 Flash 20 Older Flash unchanged

    The pattern is clear. Google is generous with Gemma and the Lite line, and stingy with the flagship Flash models. That split decides which model you should actually run.

    What has moved since this was written

    Google has shipped two more generations of Flash since. The newest head of the line is Gemini 3.8 Flash, with Gemini 3.6 Flash sitting between it and 3.5. Google’s own pricing docs list every Flash generation — 3.5, 3.6, 3.7 and 3.8 — as free of charge on the free tier, so the frontier line is still reachable at $0. What the docs do not publish is how many requests a day each one allows at that price; that is the part that still lives in your own aistudio panel, and it is the tiny test-only number, not the Gemma-sized one.

    The free tier has also widened into audio. Gemini 3.8 Flash TTS and 3.8 Flash-Lite TTS, the Gemini 3.8 Live family (including 3.8 Live Extended Thinking and the 3.1 Flash Live Preview), 3.5 Live Translate and 3.5 Transcribe all now carry a free-of-charge tier. None of those existed in this lineup when the article was first written, and none of them change the chatbot recommendation below — but they are worth knowing about if you were about to pay for voice or transcription.

    What 14,400 Free Requests a Day Is Actually Worth

    Numbers like 14,400 are abstract until you convert them into the thing you actually care about: how much chatbot traffic you can serve, and what that would cost if you paid for it.

    Volume Chat requests Rough analogue
    Per day 14,400 One message every 6 seconds, 24/7
    Per month (30 days) 432,000 ~432k conversations or ~4.3M messages
    Per year 5.26M More than a busy ecommerce store

    Here is what that volume is worth on the open market. A typical SaaS chatbot service charges $49 to $99 a month and caps you at a few hundred conversations before pushing you to a higher tier. The Google AI Studio free tier gives you 432,000 conversations a month. To get that volume from a SaaS chatbot, you would be paying hundreds of dollars a month — if those tiers even exist.

    That is the real headline hiding inside this update. The free Google AI Studio free tier is not a trial or a teaser. At this volume it replaces a subscription outright, which is exactly why a self-hosted, bring-your-own-key setup like a WordPress chatbot is so appealing: you keep the free allowance, keep your data on your own server, and drop the monthly bill entirely.

    Holographic AI interface concept for the Google AI Studio free tier
    Google is banking on developers building on its free tier.

    How Google’s Free Tier Stacks Up Against the Competition

    The Gemini free tier only matters relative to the alternatives. Each major provider runs a different model: some give you a generous API free tier, some only a friendly web chat, some nothing at all.

    Provider Free API tier Free web / app chat Best free allowance
    Google AI Studio ✅ Yes, generous Gemini app 14,400 req/day (Gemma 4)
    OpenAI ⚠️ Very limited ChatGPT (usage-capped) Capped chat, small API credit
    Anthropic ❌ No free API Claude.ai (usage-capped) Web chat only
    Mistral ✅ Experiment tier Le Chat Rate-limited experiment plan
    xAI (Grok) ❌ No free API Grok app (limits) Web/app chat only

    For anyone building an API-connected product, Google is the only major player handing out a genuinely usable free API allowance at this scale. That is the strategic angle worth understanding: the free Google AI Studio free tier is not a marketing trick, it is a land grab for developers who build on top of models. The catch is that it only pays off if you adopt a setup where you keep the savings. A self-hosted chatbot captures the entire allowance; a hosted SaaS chatbot sits in the middle and skims its own margin.

    Google AI Studio free tier usage data on a tablet

    Track your allowance in the aistudio rate-limit panel.

    Which Free Model Should You Use Now?

    The Gemma bump changes the default recommendation. Before, you picked between volume (Gemma at 1,500) and quality (Flash-Lite at 500). Now Gemma 4 gives you both the volume and a big enough allowance that the 500-request ceiling on Flash-Lite looks thin by comparison.

    Here’s the clean way to decide:

    • Gemma 4 (14,400/day) — the default. Enough volume that you never think about limits, and open-weight so your data isn’t trained on. Pick this unless you have a specific reason not to.
    • Gemini 3.5 Flash-Lite (500/day) — pick this if you want the fastest, most polished responses and your traffic is light enough that 500 requests a day is plenty.

    Most sites should now run Gemma 4 and stop there. Flash-Lite is the choice for a low-traffic site where response quality and speed beat the need for headroom.

    How to Check Your Own Free Tier Limits in aistudio

    The numbers in this article came from a live aistudio rate-limit panel. Because Google rotates limits as it ships and retires models, you should confirm what your account actually gets before you build around a number. Here is the walkthrough.

    1. Open aistudio.google.com and sign in with the same Google account you use for the API key.
    2. Find the rate-limits or usage panel. Google moves this menu around from time to time, but it lives under the account menu, labeled something like Rate limits or Usage.
    3. Look up the model you plan to use. Read the free tier request limit next to its name. That number, not the one in a blog post, is the one that governs your site.
    4. Note the reset window. Some limits reset daily, others on a rolling window, so check whether your cap is per day or per hour.

    The habit matters more than the specific number. Every couple of months, open that panel and re-check the model you run. Google raised Gemma’s free tier twice in recent months. Checking a panel once a month costs you thirty seconds and keeps a $0 hosting setup honest.

    Server tower powering the Google AI Studio free tier

    The infrastructure behind 14,400 free requests a day.

    Gemma 4 vs Gemini 3.5 Flash-Lite for a Chatbot

    If you are choosing between the two free models for an actual production chatbot, here is the full trade-off, not just the headline numbers.

    Consideration Gemma 4 Gemini 3.5 Flash-Lite
    Free requests / day 14,400 500
    Speed Very good Fastest in the lineup
    Output quality Excellent Excellent, tuned for speed
    Weight Open-weight Closed model
    Data trained on your prompts? No Policy-dependent
    Best for Default, high-volume Low traffic, max polish

    For most chatbot use, choose Gemma 4. The 14,400-request allowance means you never gate your site on usage, and open-weight models give you a cleaner story about data privacy, which matters if your chatbot handles customer conversations or lead capture.

    Choose Gemini 3.5 Flash-Lite if your traffic is genuinely light, you want the lowest possible response latency, and you would rather have the most refined short answers than the biggest allowance. The right mental model is: Gemma 4 is the production workhorse; Flash-Lite is the premium-lightweight for small flows.

    Open-Weight vs Closed Models: Why It Matters Here

    This update quietly pushes Google’s open-weight line to the top of the free tier, and that is worth pausing on. Open-weight models publish their weights and run on infrastructure you control. Closed models keep their weights private and only serve you through the provider’s API.

    For a self-hosted chatbot, the practical difference shows up in two places. First, data handling: an open-weight model that processes your conversations on your own server gives you a cleaner privacy story for GDPR and customer trust than sending every message to a black-box vendor. Second, lock-in: if you host an open-weight model, you can migrate it to any provider or your own hardware. A closed model keeps you dependent on that vendor’s API, pricing, and rate limits.

    The free Google AI Studio free tier has both kinds of models side by side, which lets you test the quality of open-weight Gemma against closed Gemini before you commit. That is a genuinely useful position to be in: you get to compare, then pick the path that keeps your data and your costs under your control.

    Switching in a WordPress Chatbot Takes Seconds

    If you run YakWP on WordPress, both changes are already live in your settings. YakWP lists every free Gemini model with its daily allowance right next to the name, so you can see the new numbers without looking anything up.

    The switch is a two-step change:

    1. Go to YakWP settings and confirm the provider is Google Gemini.
    2. Open the model dropdown and pick Gemma 4 31B (for volume) or Gemini 3.5 Flash Lite (for speed).

    That’s it. No new API key, no billing change, no plugin update. Your existing AIza key from aistudio works as-is. If you don’t have one yet, grab it free at aistudio.google.com/apikey — about 30 seconds, no credit card.

    If you’re still deciding whether to self-host a chatbot at all, the BYOK explainer covers the why, and the 5-minute setup guide walks through the install.

    Data center rack of servers for free AI models

    Self-hosted means the model runs where your data lives.

    What These Changes Don’t Mean

    Two caveats so the update doesn’t read as bigger than it is.

    The frontier Flash models are still test-only. 3.5, 3.6, 3.7 and 3.8 Flash all stay in the tiny test tier on the free tier — 20 requests a day in the panel figures used here. Google is being generous with Gemma and the Lite line, not the flagship models, and a newer generation does not change that.

    Google still doesn’t publish the per-model free limits. The pricing docs do say which models are free of charge — that is how the new Flash, TTS and Live models above were confirmed — but the actual requests-per-day caps live in your aistudio rate-limit panel and nowhere else. The daily numbers in this article are from a live panel; if yours differ, trust your panel.

    Free tiers change. Google has doubled and ten-x’d allowances before, and it has trimmed them too. If you build a business on the Google AI Studio free tier, keep an eye on that rate-limit panel, and keep the option of a paid key open as a fallback.

    Frequently Asked Questions

    Did Gemma 4’s free tier really jump to 14,400 requests a day?

    Yes. It moved from 1,500 to 14,400 free requests a day, a nearly 10x increase. It’s now the largest free allowance in Google’s lineup by a wide margin.

    Is Gemini 3.5 Flash-Lite free?

    Yes, at 500 requests a day on the Google AI Studio free tier — the same allowance as the older 3.1 Flash-Lite.

    Should I use Gemma 4 or Gemini 3.5 Flash-Lite for my chatbot?

    Gemma 4 for most sites — the 14,400-request allowance removes the limit from the equation. Gemini 3.5 Flash-Lite if you want the fastest, most polished responses and your traffic fits within 500 requests a day.

    Do I need a new API key for either change?

    No. Your existing aistudio key works for both Gemma 4 and Gemini 3.5 Flash-Lite. Just select the model in your chatbot’s settings.

    Can I use more than one model on the free tier?

    Yes. The Google AI Studio free tier each model gets its own daily allowance, and they don’t share a single bucket. You can run Gemma 4 for general traffic and route to Gemini 3.5 Flash-Lite when you want the fastest replies, both at no cost.

    Is the free tier available outside the Google AI Studio free tier rate limits?

    No. The limits in this article apply to aistudio’s free tier. If you move to a paid Google Cloud or Vertex AI key, billing is per-token and you pay for the volume you actually use.

    Do the free tier limits apply to everyone?

    Your exact limits can differ from the numbers here depending on account age, region, and whether you verify a payment method. The published August 2026 figures are a good baseline; your aistudio rate-limit panel is the final word.

    What happens if I exceed the free allowance?

    Requests over the limit start failing with a rate-limit or quota error rather than silently billing you. For a chatbot, that means the widget stops answering until the window resets, so keep an eye on usage if you approach the cap on a 500-request model.

    Is the free tier enough for a real business site?

    At 14,400 requests a day, yes for nearly every small and mid-size site. That volume covers a busy self-hosted chatbot with plenty of headroom. The main risk is the frontier Flash models at 20 requests a day, which are test-only and not suitable for production.

    Can I upgrade later without changing my chatbot setup?

    Yes. You keep the same key and simply change the model or add billing in aistudio when you outgrow the free tier. A self-hosted chatbot makes that transition a settings change rather than a re-platforming project.

    The Bottom Line

    The free tier got meaningfully better this month, and the Gemma jump is the part worth paying attention to. 14,400 free requests a day is enough to run a self-hosted chatbot on a real site for $0, forever, without ever glancing at a usage counter. Gemini 3.5 Flash-Lite is a nice speed upgrade on the side.

    Put together, the Google AI Studio free tier now beats every major competitor on API volume and is the only mainstream provider giving real developers a genuinely free, large allowance. Pair it with a self-hosted plugin and that advantage lands entirely in your pocket.

    And there is a second reason this month’s change deserves more attention than a routine model bump. It is a signal about where the free AI market is heading. Google is using a large free allowance to pull developers onto its models, and at this volume the free tier stops being a trial and starts being a product strategy that replaces paid chatbot subscriptions outright.

    The practical takeaway for a small business is short: if you run a WordPress chatbot, open your model dropdown and switch to Gemma 4. You get the biggest free allowance in the market, a capable open-weight model, and one less recurring bill. If you are still picking a chatbot stack, the BYOK explainer and the 5-minute setup guide cover the rest, and the n8n integration guide shows how to automate the leads each conversation captures.

    If you run WordPress, both are already in YakWP’s model list. See what YakWP includes or grab the free plugin and point it at Gemma 4.

  • OpenCode Go Review: 33 AI Models for a Flat $10 a Month

    ▶ Listen to this article

    OpenCode Go is a model subscription that costs a flat $10 a month, with no contract — you can cancel any time. It comes from the team behind OpenCode, and it exists to fix one specific problem: getting reliable access to good AI models without juggling a dozen provider keys.

    Programmer coding on laptop
    One subscription, many models.

    The pitch is simple. The OpenCode team tests a curated list of open models, benchmarks each one against the provider hosting it, and sells you access to the whole lineup behind a single API key. Flat ten a month, no contract. No per-token math, no rate-limit roulette, no wondering whether the model you’re calling is still alive.

    Here’s what you actually get: every model in the lineup, the exact request limits, and the real numbers on what ten dollars buys.

    What OpenCode Go Actually Is

    OpenCode Go is a flat-rate subscription. One API key, one endpoint, a curated line-up of open models. It’s the paid companion to the free OpenCode coding agent, but you don’t need the agent to use it — the API is a standard OpenAI-compatible endpoint that plugs into whatever you already run.

    OpenCode markets Go toward developers, and the model list is benchmarked for agentic work. But here’s the thing the marketing undersells: these aren’t niche coding models. They’re the same general-purpose large language models people use for everything — writing, chatbots, research, summarization, data extraction, translation, automation. Qwen, GLM, DeepSeek, Kimi, MiniMax. They write code, but they also write articles, answer customer questions, and turn messy data into clean output.

    So while the homepage says “coding models,” what you’re really buying is cheap, reliable access to good AI models. What you do with them is up to you.

    The Pricing: a Flat $10 a Month

    Every month is $10. There’s no annual contract, and you can cancel any time.

    That also means the old “$5 first month” promo is gone — but the way to shave the cost is Go’s referral credit: share your referral link, a friend subscribes to Go, and you both get a $5 usage credit applied toward your Go usage limits. It’s a credit that keeps working every time you bring someone in, not a one-time signup discount.

    But the part most people miss is the usage ceiling. The limits are:

    • 5-hour limit — $12 of usage
    • Weekly limit — $30 of usage
    • Monthly limit — $60 of usage

    You’re paying $10 a month. The monthly usage ceiling is $60. That’s the 6x multiplier OpenCode advertises — they buy reserved GPU capacity and bulk-discounted rates, then pass the savings through. For most models, the math works out to roughly six times what you paid.

    Limits are measured in dollar value, not request count, because different models cost different amounts to run. A cheap model like MiMo-V2.5 gives you far more requests than an expensive one like GLM-5.2. Here’s the full table, straight from the OpenCode’s own docs (and our notes on the same page).

    The Model Lineup: 33 Models Now (All of Them Listed Below)

    ModelRequests / 5hRequests / weekRequests / month
    Space Bunny FreeUnlimitedUnlimitedUnlimited
    LongCat 2.5 Preview FreeUnlimitedUnlimitedUnlimited
    Muse Spark 1.3 Contributor45,300113,300226,600
    Muse Spark 1.2 Contributor45,300113,300226,600
    MiMo-V2.6-Flash30,10075,200150,400
    MiMo-V2.530,10075,200150,400
    DeepSeek V4.1 Flash26,00065,000130,000
    DeepSeek V4 Flash13,00032,50065,000
    LongCat-2.011,40028,60057,200
    DeepSeek V4 Flash Vision Exp6,50016,25032,500
    GLM-5.3-Flash6,32015,79031,580
    Qwen3.8 Flash5,40013,50027,000
    Qwen3.7 Plus4,30010,80021,600
    Hy34,30010,75021,500
    GPT 6 Luna4,23010,56021,130
    MiniMax M2.73,4008,50017,000
    Qwen3.6 Plus3,3008,20016,300
    MiMo-V2.6-Pro3,2508,15016,300
    MiMo-V2.5-Pro3,2508,15016,300
    MiniMax M33,2008,00016,000
    GPT 5.6 Luna2,0505,10010,250
    Hy4 preview1,3503,3806,770
    Kimi K2.7 Code1,3503,3806,750
    Kimi K2.61,1502,8805,750
    DeepSeek V4 Pro1,0502,6005,200
    GLM-5.28802,1504,300
    GLM-5.18802,1504,300
    GLM-5.32205401,080
    Grok 4.7169423845
    Grok 4.6169423845
    Qwen3.7 Max170420840
    Qwen3.8 Max160400810
    Kimi K3110250490

    Read those top rows again. The MiMo V2.6 Flash and MiMo-V2.5 lanes each give you 150,400 requests a month, DeepSeek V4.1 Flash is back up to 130,000 after its boost returned, and even DeepSeek V4 Flash sits at 65,000. For a flat ten a month. That’s the “cheap model, tons of requests” end of the spectrum, and it’s genuinely hard to exhaust for a solo user.

    The expensive end — Grok 4.7 and Grok 4.6 at 845 requests a month, Kimi K3 at 490 — is for when you need a heavy frontier model on a specific task. You don’t run those for everything. You run them when it matters, and the cheap models carry the routine work.

    The lineup keeps growing. The newest arrivals are Grok 4.7 (which joins rather than replaces Grok 4.6), GPT 6 Luna, the MiMo V2.6 pair — Flash and Pro — and Space Bunny Free, plus LongCat 2.5 Preview Free — two free models OpenCode is running for a limited time. OpenCode now documents 33 models on the Go page; the API endpoint itself returns 43 ids, because extra lanes (a deepseek-flash alias, GLM-5, Grok 4.5, Hy3 preview, Kimi K2.5, MiMo V2 Omni and V2 Pro, MiniMax M2.5, Qwen3.5 Plus, and an undocumented stealth model listed as omen-alpha) are routable without ever appearing in the marketing table. Treat the documented 33 as the supported set — and if you value zero-retention guarantees, stay away from the unofficial ids entirely, since an undeclared model publishes no privacy row.

    Worth knowing before you wire it into your own stack: Grok 4.6 is listed with its own limits and prices, but on the plain OpenAI-compatible endpoint it currently answers with an “endpoint is unavailable” error. It works through OpenCode’s own client; if you’re calling the API directly, pick one of the other models.

    Why Some Models Give You So Few Requests

    The 6x multiplier isn’t uniform. OpenCode is honest about this in their docs: for most models, bulk discounts and reserved GPU capacity make the 6x work. For a few — usually new models or ones already priced cheaply by their own provider — OpenCode hasn’t been able to negotiate a better rate, so the multiplier is lower.

    Either way, you still get slightly more than paying the model provider directly. The $60 monthly ceiling is the ceiling, not the typical experience. Most people using a mix of cheap and expensive models will land somewhere in the middle and never touch the limit.

    One detail that trips people up: the usage ceiling is per model, not one shared $60 pot. Most models carry the full $60, but the ones OpenCode couldn’t negotiate a bulk rate on are capped lower — GLM-5.3, Kimi K3, Grok 4.7, Grok 4.6, Qwen3.8 Max, GPT 6 Luna, GPT 5.6 Luna, DeepSeek V4 Pro, MiMo-V2.6-Pro, MiMo-V2.5-Pro and DeepSeek V4 Flash Vision Exp sit at $15 a month, while DeepSeek V4 Flash, Qwen3.8 Flash, Qwen3.7 Max and Hy4 preview sit at $30. DeepSeek V4.1 Flash is back at the full $60 while its boost runs, and Space Bunny Free carries no limit at all. Per model the 5-hour and weekly caps scale the same way: 20% and 50% of the monthly figure. It only matters if you plan to run one model for everything — check that model’s ceiling before you commit.

    One more lever worth knowing: the DeepSeek models bill at half price outside peak hours, so the same monthly ceiling stretches roughly twice as far when your workload lands in the cheap window. Peak is 01:00–04:00 and 06:00–10:00 UTC on weekdays, and weekends are off-peak the whole way through. If any of your work is batchable, scheduling it outside those windows is free headroom on exactly the models most people lean on hardest.

    Zero Data Retention (For Almost Everything)

    The privacy table is short and unusually clean. Of the 33 models in the lineup, 27 carry zero-day data retention — your prompts and responses are not logged and not used for training.

    The six exceptions are flagged plainly:

    • Grok 4.7 and Grok 4.6 — 30-day retention, and enabling zero-data-retention disables some API features.
    • GPT 6 Luna and GPT 5.6 Luna — abuse monitoring logs kept up to 30 days.
    • Muse Spark 1.3 and 1.2 Contributor — the trade is explicit: heavily discounted tokens in exchange for Meta training future models on your prompts and completions. Not zero-retention, and not available in every region.

    DeepSeek models have zero-day retention through an agreement renewed monthly — the current cover runs through September 30, 2026, so if that renewal ever lapses, this paragraph is the first thing to re-check. If you’re feeding proprietary content into a model, this is the table you should care about, and OpenCode actually publishes it.

    Why Cheap, Reliable Model Access Matters for Everyone

    If you run a website with an AI feature — a chatbot, a content generator, anything that calls a model — you already know the drill. You bring your own API key. The question is always which model to point it at, and what it costs per request.

    If you’re a writer, a freelancer, a small business owner, or anyone who leans on AI for daily work, the same logic applies. You don’t want to think about which provider is throttling you today. You want one key, one price, and models that actually respond when you call them.

    This is where the flat-subscription logic pays off. A flat ten a month for a curated line-up of tested models, with a $60 usage ceiling, beats juggling three free-tier keys that throttle you mid-job. Whether you’re writing content, answering customer questions, or building something that calls an API, predictable flat pricing beats per-token anxiety.

    YakWP itself is built on the same philosophy — you own the plugin, you bring your key, there’s no recurring SaaS fee for the widget itself. The missing piece has always been the model access. A cheap flat-fee subscription closes that gap.

    How I Use It

    My setup routes different tasks to different models. Heavy reasoning goes to DeepSeek V4 Pro or GLM-5.3. High-volume writing, classification, and extraction go to MiMo-V2.5, where the 150K monthly requests mean I stop thinking about limits entirely.

    The API is a standard OpenAI-compatible endpoint. Changing a base URL and an API key is the entire integration.

    import openai
    
    client = openai.OpenAI(
        base_url="https://opencode.ai/zen/go/v1",
        api_key="your-opencode-go-key",
    )
    
    response = client.chat.completions.create(
        model="deepseek-v4-pro",  # or deepseek-v4-flash, glm-5.2, qwen3.7-plus...
        messages=[{"role": "user", "content": "Summarize this document."}],
    )
    

    If you’re on OpenCode itself, you run /connect, pick OpenCode Go, paste the key, and /models shows everything available.

    Sign up at opencode.ai/go — subscribing through my link gets you a $5 usage credit.

    When Not to Bother

    Three honest reasons to skip Go:

    1. You only need one model. If your entire workload is DeepSeek V4 Flash, you might be fine on a free tier somewhere. Go earns its keep when you want a mix of cheap fast models and expensive frontier models behind one key.
    2. You need a specific proprietary model. Go covers open models only. If your workflow is built around Claude or a specific GPT, this isn’t a replacement.
    3. You’re already happy with free-tier scavenging. If you don’t mind juggling keys and hitting rate limits, Go is a convenience you don’t need. It’s for people who’d rather pay $10 to try it than think about it.

    What Changed Since the Last Update

    Provider line-ups move, which is why this review gets re-checked against OpenCode’s own endpoints rather than left to age. Here is what changed since the previous version:

    • The roster is up to 33 documented models. LongCat 2.5 Preview Free is the newest arrival — a second free, unlimited lane (262K context) running for a limited time, alongside Space Bunny Free. The privacy table grew with it: 27 of the 33 models now carry zero-day retention.
    • The DeepSeek V4.1 Flash boost came back. The promotional ceiling that ended in September has returned: the model is back at a $60 monthly limit and 130,000 estimated requests a month, four times the standard lane. OpenCode runs these boosts on and off, so verify the ceiling on the day if you plan around it.
    • One lane got tighter. Qwen3.7 Max halved, from 1,690 estimated requests a month to 840, and now sits in the $30 ceiling tier. Nothing else in the lineup moved.

    The DeepSeek zero-retention agreement is renewed monthly — the current cover runs through September 30, 2026 — which is the part of this review that needs the most frequent verification.

    FAQ

    Is OpenCode Go the same as the OpenCode agent?

    No. The agent is free and open-source. Go is a separate paid subscription for model access. You can use Go with any OpenAI-compatible client, not just OpenCode.

    What happens if I hit the $12 five-hour limit?

    Requests get rate-limited until the window resets. Your subscription isn’t cancelled and you’re not charged extra. If you have Zen credits, you can enable “Use balance” and it falls back to your balance instead of blocking.

    Do the models get used for training?

    For 27 of the 33 models, no. Data retention is zero days. Grok 4.7 and 4.6, GPT 6 Luna and GPT 5.6 Luna, and both Muse Spark Contributor models are the exceptions noted above — the last two train on your prompts by design.

    Does the OpenCode v2 release change anything about Go?

    No. Go is a subscription to a model endpoint, not a feature of the agent. Version 2 of the coding agent changed the app — new plugin and server APIs, a global config file — while the Go endpoint and your API key stayed exactly as they were. You can use Go with the v2 agent, the older v1 agent, or any other OpenAI-compatible client.

    Are these models only for coding?

    No. They’re general-purpose models. OpenCode benchmarks them for agentic work, but they handle writing, summarization, translation, chatbots, and data extraction just as well. The “coding” label is about how they’re selected, not what they can do.

    How much does OpenCode Go cost?

    $10 a month, flat, and you can cancel any time — there’s no contract and no first-month promo. The discount now runs through referrals: when a friend subscribes via your referral link, you both get a $5 usage credit toward your Go usage limits.

    How do I sign up?

    Sign in at opencode.ai/go, subscribe, copy your API key, and point your client at the endpoint above.

    The Honest Bottom Line

    A flat $10 a month for a curated line-up of open models, a $60 monthly usage ceiling, and a published zero-retention privacy table. If it’s not for you, cancel any time. And when you refer a friend who subscribes, you both get a $5 usage credit — so each referral trims the effective price.

    If you’ve been fighting free-tier rate limits or juggling three API keys, this is the single subscription that replaces all of that. If you run an AI-powered website, it’s the cheap, predictable model access that makes your own BYOK setup actually affordable. I pay full price for mine and I don’t plan to cancel.

    Want to try it? The discount now runs through the referral program. Subscribe through this link and you and I both get a $5 usage credit toward our Go limits: opencode.ai/go. It doesn’t cost you anything extra — and my own link already pulled in a run of sign-ups off a single Reddit post, so I can vouch that it converts.